MLX-Diffusion On Mac

MLX-Diffusion : Yet another open source image generator on Apple Silicon

MLX-DIFFUSION • SOVEREIGN LOCAL GENERATIVE STUDIO

Unleashing MLX-Diffusion on Apple Silicon

👤 By Ouinche 💻 Hardware: Mac M1 16GB Unified Memory 🚀 Dual-Engine: MLX Diffuser & mflux 🔓 License: Open-Source on GitHub

Don’t pay to generate censored image online ! Even with an 5 year old MAcBook M1 16Gb

What if you could take the absolute bleeding-edge of open-weights AI—massive 9-billion and 13-billion parameter models—and run them directly on the Mac sitting in front of you? Fast, free, uncensored, and private.

Today, we introduce MLX-Diffusion: an open-source generative studio built for hobbyists and researchers that turns your Apple Silicon Mac into a sovereign AI creative laboratory.

1. Interface & Technical Analysis: What It Does — And What It Does NOT Do

Before diving into empirical performance metrics, it is vital to understand the architectural foundation powering MLX-Diffusion.

What the Application Does (Features & Architecture)

  • Dual-Engine Local Generation: Powered natively on Apple Silicon by a robust dual-engine stack utilizing MLX Diffuser (for SDXL architectures) and mflux (for Flow-matching DiTs and Wan2.1). Both engines compile directly into Metal Performance Shaders, eliminating bloated runtime abstraction layers.
  • Intuitive, UnProfessional UI: A sleek, dark-themed interface resembling professional creative software, divided into an ergonomic parameter panel and a dedicated « Studio Canvas » equipped with built-in High-Resolution Visual Comparators and real-time generation previews.
  • SOTA Architecture Support: Flawlessly runs standard SDXL checkpoints alongside cutting-edge open-weight architectures like Flow-matching DiTs (FLUX.2-klein 4B & 9B, Z-Image Turbo 6B) and Wan2.1 (Krea 2 Turbo 13B) and Qwen-Image-2.1 ( ok only in 768×512 and Q4 quantized but Qwen-Image-2.1 at all.
  • Absolute Data Sovereignty (« Stealth Mode »): A core privacy feature: the Stealth Mode (No generation metadata) toggle. When active, it guarantees that absolutely zero generation metadata (prompts, seeds, CFG, models) is embedded into the exported image file. Your thoughts and creative recipes never leave your local drive.
  • Automatic Civitai Metadata Formatting: When sharing is desired, MLX-Diffusion automatically formats lossless PNG text chunks and EXIF tags to strictly comply with Civitai and Automatic1111 standards, enabling effortless drag-and-drop ingestion into Civitai galleries.
  • Frictionless Hobbyist Launch: Open-source on GitHub with zero python environment hell. No broken Conda environments or compiling C++ dependencies; simply clone and launch via a single bash command: ./Run.sh. ( NDLR : KEK ! See below )
  • Comprehensive Workflow Tools: Built-in multi-LoRA manager with auto-unloading on model swaps, upscaling suite featuring AI Neural 2x (SeedVR2 latent model) and Fast 4x Lanczos, multi-image reference inputs, and a fast local image browser.
  • Granular Parameter Control: Full interactive control over model checkpoints, image dimensions (portrait, square, landscape), step trajectories, Guidance scale (CFG), seed locking/randomization, and batch scheduling.
  • Deterministic Memory Clamping: Active denoise wired-memory clamping (limiting denoise allocations to 6.5–7GB), lazy pipeline unloader, and compiled Metal VAE decoders prevent macOS SSD swap thrashing even when generating at high resolutions.

What the Application Does NOT Do

  • No Cloud Processing: Relies 100% on your local Apple Silicon hardware. Zero cloud servers, zero background analytics, and zero monthly subscriptions.
  • Zero Content Moderation / Censorship: Completely offline. There are no hidden API safety filters, no blocked vocabulary, and no centralized gatekeepers policing your creative workflow.
  • Not an unoptimized PyTorch MPS wrapper: Standard PyTorch on macOS (torch.device("mps")) frequently leaks memory and misses custom fused Metal kernels. MLX-Diffusion executes native MLX array operations.
  • Not an unrealistic claim: A 16GB Mac cannot run 70B unquantized FP16 models. MLX-Diffusion achieves fluid local generation through disciplined 4-bit fused quantization and calibrated step trajectories.

2. The Grand SOTA Benchmark (Apple Silicon M1 16GB)

To establish empirical truths, the Apple Silicon Laboratory benchmarked ten state-of-the-art model configurations across ten canonical test prompts representing diverse visual challenges (environmental portraiture, Scandinavian landscapes, wildlife macro textures, glass architecture, and night urban lighting) at 512×768 resolution under fixed seeds (1001–1010) — with the brand-new Qwen-Image 2.1 (7B) matching the same 512×768 canvas as every other configuration (Qwen’s 64-channel RGBA VAE handled it without OOM; only 1024² exceeds the 16GB M1’s bf16 VAE decode headroom). All SDXL checkpoints and distilled LoRA adapters tested are available on Civitai.

# Model Configuration Engine & Architecture Steps CFG Avg Gen Time Speed Core Architectural Strength
1 Juggernaut XL Lightning SDXL MLX 4 1.0 9.73s 2.43 s/step Rapid prototyping (~10s), balanced composition. Available on Civitai.
2 RealVisXL V5.0 Lightning SDXL MLX 6 1.5 26.97s 4.50 s/step Skin micro-textures and soft lighting in under 27s. Available on Civitai.
3 RealVisXL V5.0 + Hyper-SD SDXL MLX 8 2.0 41.64s 5.21 s/step Deep textural density on full base UNet via Civitai.
4 Juggernaut XI v11 + Hyper-SD SDXL MLX 8 2.0 42.93s 5.37 s/step Surgical precision on metals, gears, and dynamic range on Civitai.
5 FLUX.2-klein 4B mflux (FlowMatch) 4 1.0 53.28s 13.32 s/step Optical physics, glass refraction, zero negative prompts.
6 FLUX.2-klein 9B mflux (FlowMatch) 4 1.0 107.04s 26.76 s/step Museum-grade 9B DiT, 100% local on 16GB memory.
7 Z-Image Turbo 6B mflux (FlowMatch) 8 1.0 170.44s 21.31 s/step Sharp geometric perspective and architectural alignment.
8 Krea 2 Turbo 13B (Distill) Wan2.1 + LoRA 4 1.0 250.83s 62.71 s/step Rich tactile surface rendering, cinematic warm lighting.
9 Krea 2 Turbo 13B (Native) Wan2.1 Native 8 1.0 368.91s 46.11 s/step Uncompressed trajectory with maximum specular precision.
10 Qwen-Image 2.1 mflux Qwen (q4) 20 1.0 457.8s 22.9 s/step Compact 7B single-stream DiT, Qwen3-VL text encoder, RGBA VAE — coherent alignment across all ten scenes at 512×768.

⚡ High-Resolution Visual Comparator: SOTA Arena (Cross-Model)

Welcome to the Grand SOTA Arena. Select any benchmark prompt from the buttons below, then choose any two models from the Left and Right dropdowns to compare them directly. Drag the center slider to inspect fine micro-textures, specular highlights, and optical physics side-by-side. You can also switch to DeepCache Lab to inspect 4-step vs 12-step caching.

⚡ High-Resolution Visual Comparator
Benchmark Scene Seed: 1001
Loading scene prompt…
Duel: Model Comparison Direct Comparison
Right Image Right Left Image Left
⮜ ⮞

💡 Interactive Grand Arena: Click any scene pill above to switch prompts. Choose any two models from the LEFT and RIGHT dropdowns to compare them head-to-head. Drag the divider to inspect differences at full resolution.

3. Open Source & Quick Start

MLX-Diffusion is free and open-source (MIT) on GitHub (github.com/OuincheWinch/MLX-Diffusion) — every benchmark above was generated locally with it. Requirements: an Apple Silicon Mac (M1–M4, 16GB+ unified memory recommended), macOS, Node.js 18+, and ~2–3 GB free disk for the first model download (one-time, into the Hugging Face cache).

0. Download

git clone https://github.com/OuincheWinch/MLX-Diffusion.git

1. Install

From the repo root, create the two Python virtual environments (both are required — the main engine venv/ and the isolated SDXL engine venv-sdxl/):

cd MLX-Diffusion
python3 -m venv venv
python3 -m venv venv-sdxl

Install the Python dependencies into each venv:

./venv/bin/python -m pip install -r backend/requirements.txt
./venv-sdxl/bin/python -m pip install -r backend/requirements-sdxl.txt

Install the frontend dependencies:

cd frontend && npm install && cd ..

2. Run

Launch MLX-Diffusion (backend port 8001, frontend port 5174, browser opens automatically). Press CTRL+C in the terminal to close it:

./run.sh

run.sh uses ./venv/bin/python -m uvicorn main:app and keeps the Mac awake with caffeinate during long renders. First generation downloads the model weights once (~2–3 GB, allow ~20 min); afterwards it runs 100% offline.

3. Your first prompt

Suggested starting prompt with FLUX.2-klein 4B, Z-Image Turbo 6B or Krea 2 Turbo 13B (4 steps for FLUX/Krea-distill, 8 steps for Z-Image):
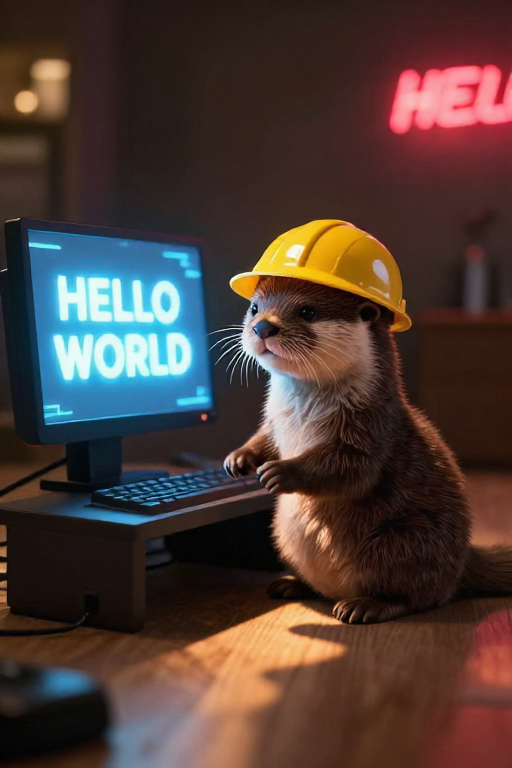
A mischievous baby otter wearing a tiny yellow developer helmet, sitting in front of a futuristic glowing computer setup. The glowing computer screen clearly displays the words « HELLO WORLD » in vibrant neon text. Warm studio lighting, shallow depth of field, 8k resolution, cinematic photorealism. [Image 1]

HELLOWORLD render

In-context reference ([Image 1]): the tag at the end conditions the generation on a reference image, but you must load that image into the reference tray first, and only FLUX.2-klein 4B accepts image input. On Z-Image, Krea 2 or SDXL the studio refuses the prompt with: Cannot read "HELLOWORLD.png" (this model does not support image input). Either switch to FLUX.2-klein 4B or remove the [Image N] tag.

4. Uninstall (full removal) when needed

Ensure your terminal is open inside the project folder you wish to remove (check the path twice!):

cd /path/to/your/MLX-Diffusion
cd .. && rm -rf MLX-Diffusion

Purge the leftover caches so nothing lingers on the machine:

# purge pip cache (clears downloaded wheels and packages)
python3 -m pip cache purge

# clear npm global cache
npm cache clean –force

5. Development mode (2 terminals)

./dev-backend.sh  # FastAPI backend, port 8001, hot reload
cd frontend && npm run dev  # Vite frontend, port 5174, hot reload

Free stuck services: lsof -ti :8001,5174 | xargs kill -9 — ports are fixed at 8001 / 5174.

4. Tailored Prompting Rules by Architecture

Prompt engineering is not one-size-fits-all. Each architecture responds to distinct syntactic and stylistic conventions:

  • SDXL Models (Juggernaut XL, RealVisXL): Respond best to optical framing tags (85mm f/1.4, Hasselblad portrait, soft studio rim light) paired with an explicit negative prompt (ugly, deformed, blurry, bad anatomy) to prune unwanted latent modes.
  • FLUX.2-klein (4B & 9B): Requires continuous descriptive prose. Negative prompts are mathematically unsupported in guidance-distilled flow matching; describe textures, reflections, physical interactions, and lighting geometry explicitly.
  • Krea 2 Turbo (Wan2.1): Thrives on concrete tactile nouns (e.g., coarse fur, brushed steel, wet asphalt, warm sunset sidelight) and cinematic depth cues.
  • Z-Image Turbo: Excels when horizon lines, geometric vanishing points, and structural object relationships are articulated cleanly in structured sentences.
  • Qwen-Image 2.1: The compact 7B single-stream DiT (Qwen3-VL text encoder, 64-channel RGBA VAE) prefers the same continuous natural prose as FLUX flow-matching — explicit negative prompts are supported (guidance auto-raises to 3.0 when used) and its 20-step linear sampling delivers the full compositional spectrum without collapse.

5. Architectural Conclusion & Sovereign AI

On an Apple Silicon Mac equipped with 16GB of unified memory, local generative diffusion has graduated from experimental toy status into a reliable, uncensored, sovereign creative workstation.

  • For Ideation & High Throughput: Juggernaut XL Lightning (~10s per generation) is the undisputed speed benchmark. Grab weights on Civitai.
  • For Organic Portraiture: RealVisXL V5.0 Lightning (27s at 6 steps) provides industry-grade skin texture and expressive depth on Civitai.
  • For Complex Optics & Global Coherence: FLUX.2-klein 4B and 9B (53s to 107s) deliver museum-grade physical light transport without negative prompt tuning.
  • For Cinematic Tactile Renders: Krea 2 Turbo 13B (Wan2.1 architecture) provides deep shadows, warm grading, and exceptional atmospheric volume.
Reclaim Your Creative Sovereignty: Stop renting AI cycles and submitting your imagination to third-party cloud filters. With MLX-Diffusion — free and open-source at github.com/OuincheWinch/MLX-Diffusion — launch via ./Run.sh and experience 100% private, uncensored generation.

Explore thousands of community checkpoints and LoRAs on Civitai. All benchmark generations produced locally using MLX-Diffusion on Apple Silicon.
Cooking MLX-Diffusion : Local image generation on M1 16Gb

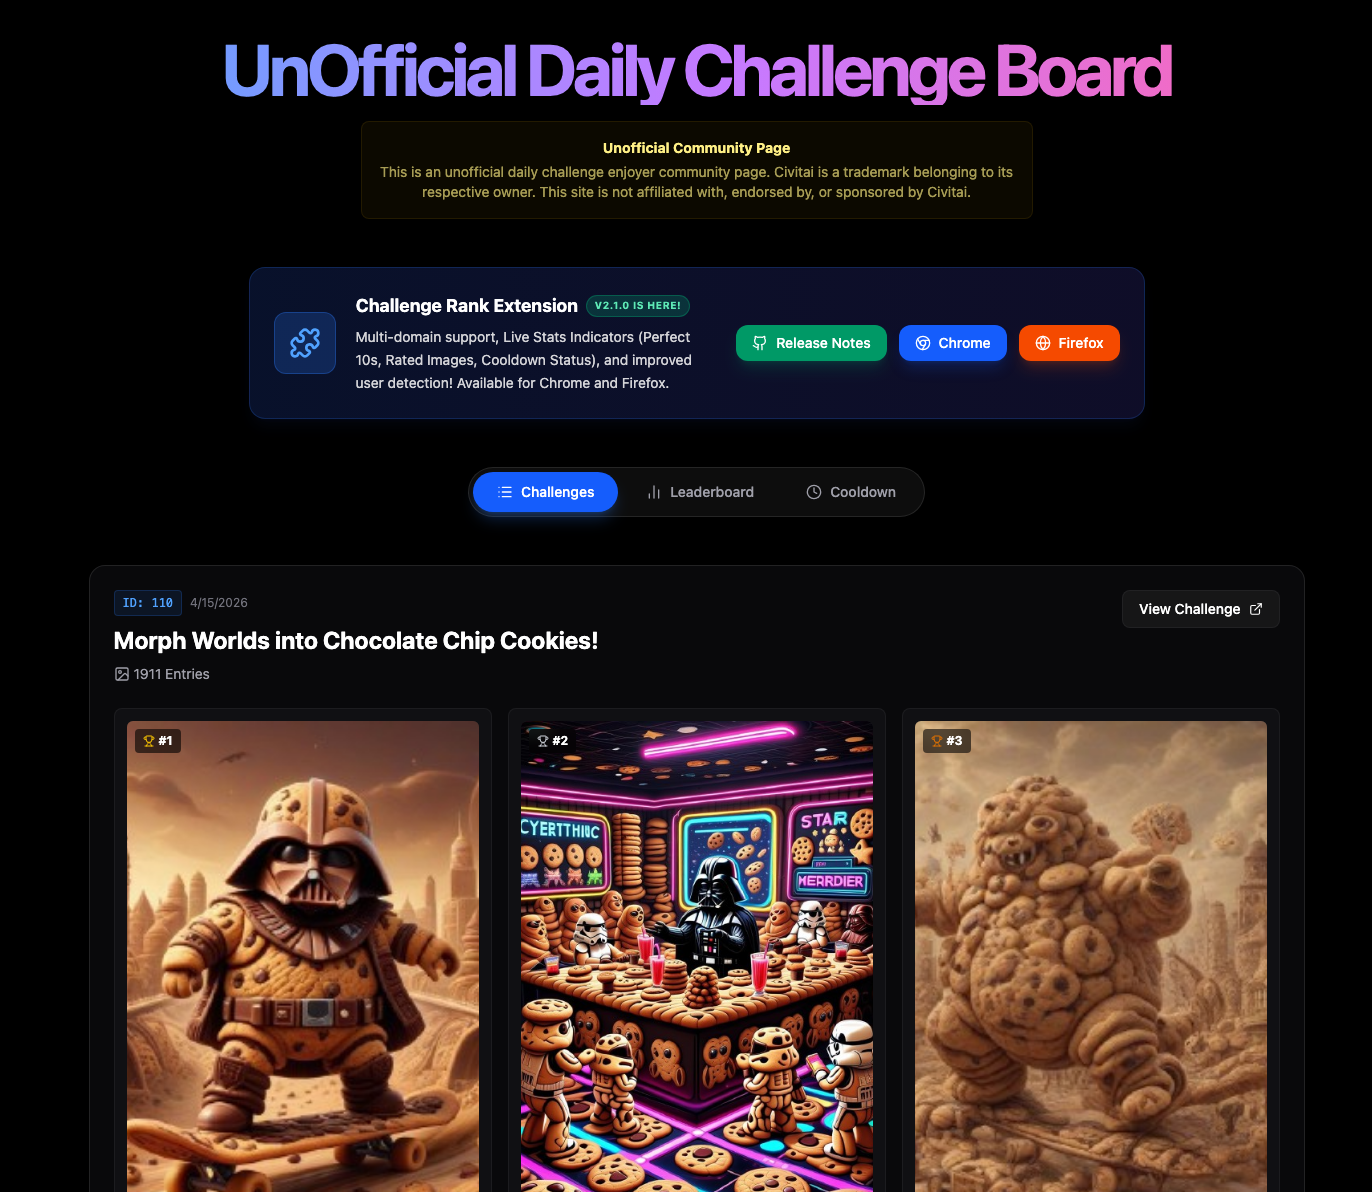
Civitai UnOfficial daily challenge environment update

🚀 Challenge Rank Extension v2.1.0 : Official Firefox Support! 🏆

Hey everyone!

We’ve got a massive update for the Challenge Rank Extension (now officially on Firefox!) and some big quality-of-life improvements to the Daily Challenge Leaderboard.

If you’re tired of scrolling forever to find the top entries or want to know exactly why an image scored what it did, this one’s for you.


🌟 What’s New in the Extension (v2.1.0)

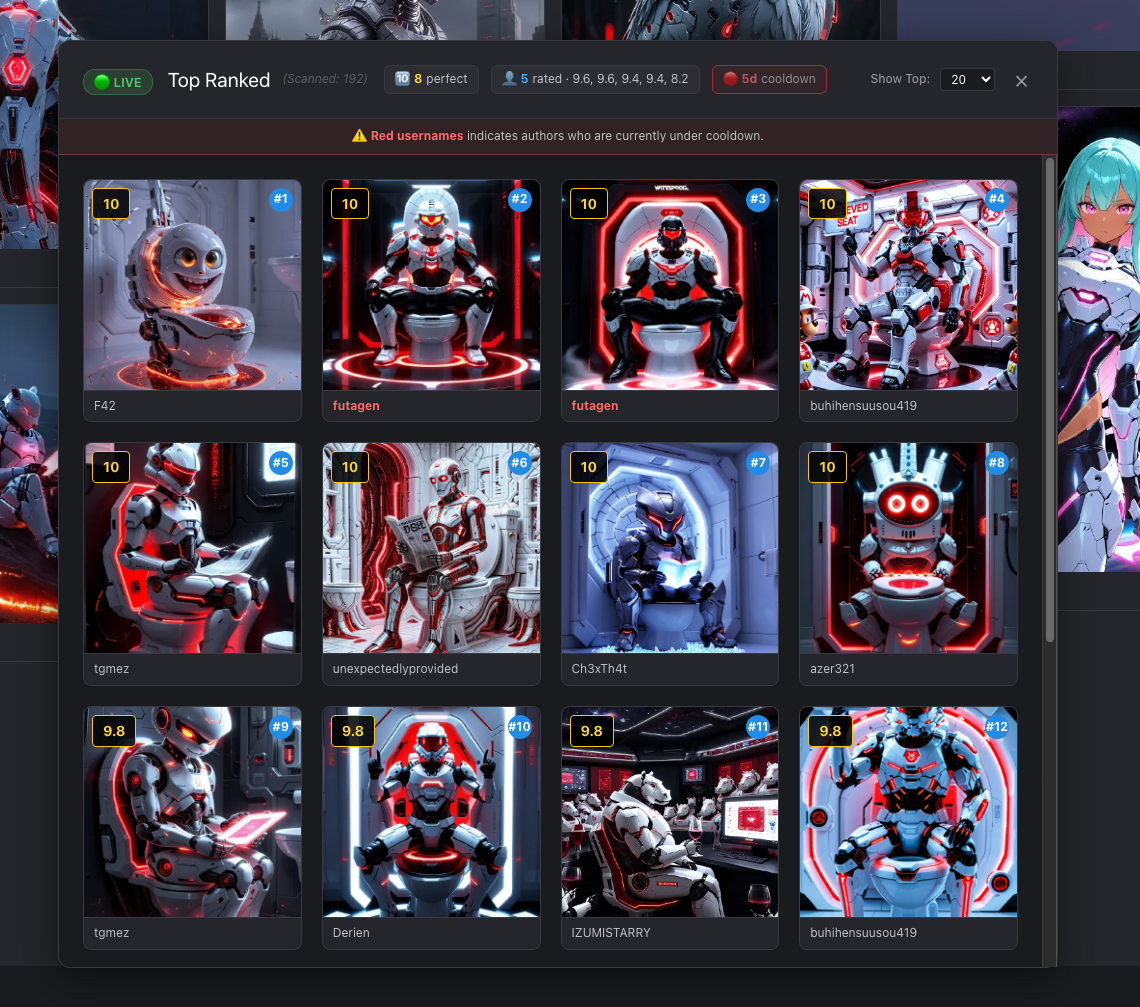
Challenge Rank V2.1.0 : New features

We’ve overhauled the overlay to give you way more context while you’re browsing:

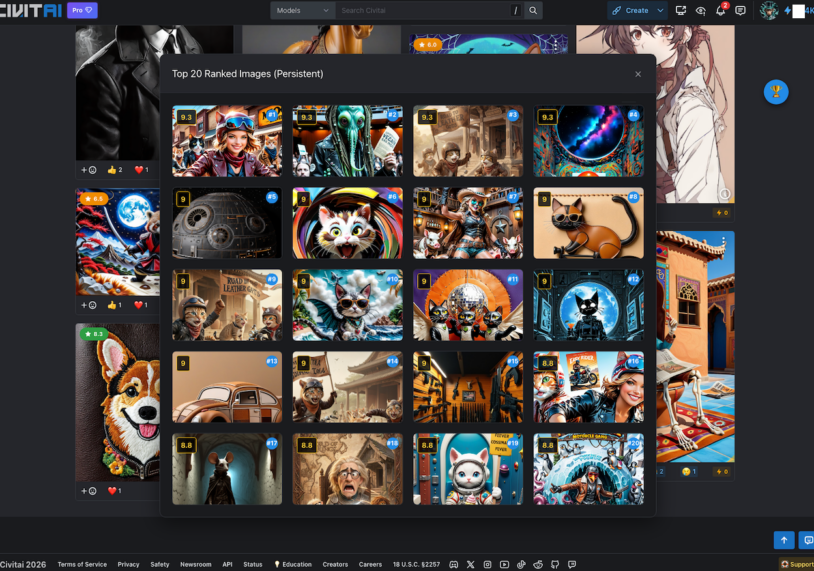
Gather in one place all the top rated images

  • ⚙️ Custom Top N: You aren’t stuck with the Top 20 anymore. Toggle between the Top 10, 20, 50, or 100 directly from the dropdown.

  • 📊 Live Stats: The header now tracks « Perfect 10s » in real-time( Cause we know that thoses days @CivBot tends to rate dozens images with a 10. It also detects your login and shows a quick summary of your own rated images.

  • 🎨 Theme Hints: We added the specific Theme Elements to the top of the overlay so you can see exactly what the judges were looking for without switching tabs ( civitai didn »t disclose this informations anymore ) .

  • ⏳ Cooldown Tracking: To keep things transparent, the extension now syncs with the site to show who is currently on a winner’s cooldown. Their names will show up in 🔴 RED in the overlay ( may or may not working depends … ) Btw you have your Cooldown status displayed 100% time while logged.

  • Support news civitai websites : .com, .green, .red

  • 🦊 Firefox is Live: We are officially verified! No more manual installs for Firefox users.


🌐 Leaderboard Site Upgrades

The UnOfficial site at ouinche.com/dailychallenge just got just updated :

Fully support new .com, .green, .red civitai websites

https://www.ouinche.com/dailychallenge/#leaderboard can now directly be linked from outside.

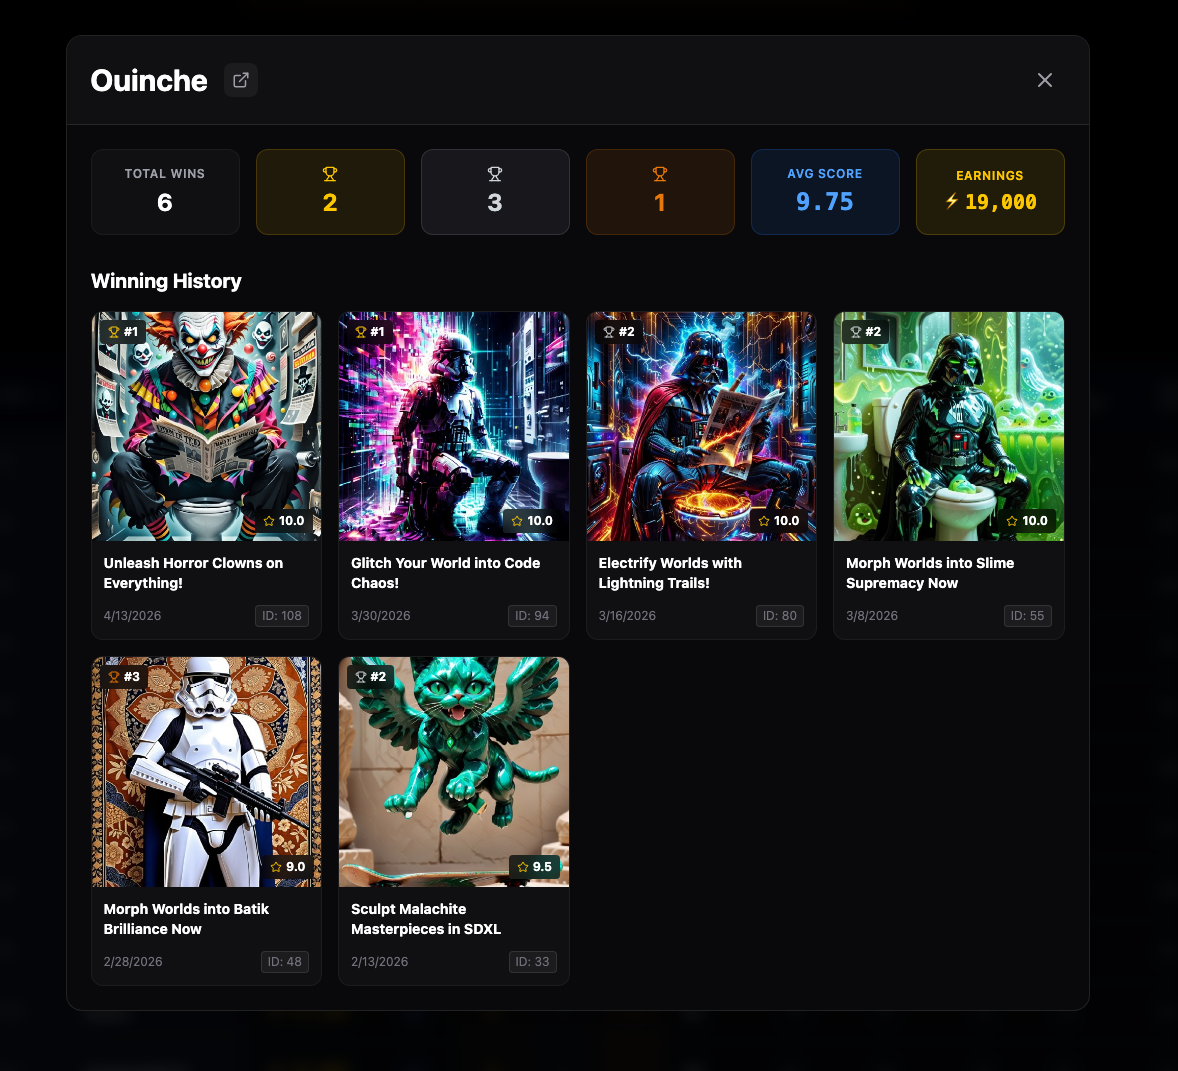
and now have Clickable User Profiles.

Just click any username on the leaderboard to pull up their full* history.
here my personnal records

https://www.ouinche.com/dailychallenge/#cooldown can directly be linked to see who’s under cooldown 

If you are found of Daily Challenge statistics, I recommend you to check https://dcd.legandor.com/ by Moonbear_AIArt


📥 Grab the Update

If you already have it, your browser should update it automatically soon. If you’re new:

Good luck with the next challenge—hope to see some of you at the top of the leaderboard! ✨


Disclaimer: This is a community project and is not affiliated with or endorsed by Civitai.

FLUX.2[KLEIN]9B Dressed up for party | reference images use case

Earlier this atfernoon I was really hyped by TRYON Lora presentation https://huggingface.co/fal/flux-klein-9b-virtual-tryon-lora

So I decide to try something, ….

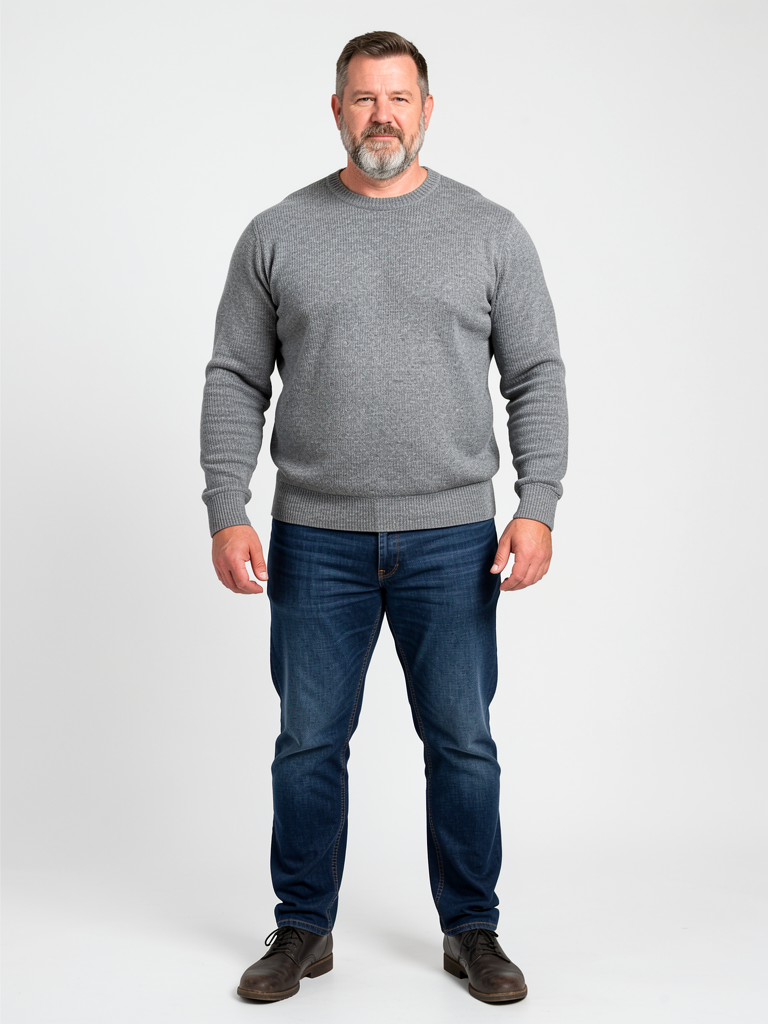
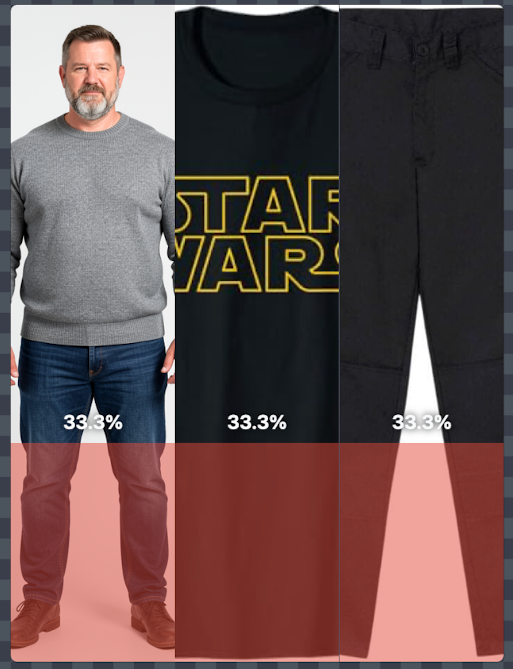
First generation with FLUX.2[KLEIN]9B of my mannequin, basic big dude with gray sweater and blue jean

PROMPT :

full body photography from head to toe, Joe ,1,95 meter 120 kg white male, muscular, 45 yo, short hairs, salt'n'pepper beard, standing in gray sweater,

Steps: 4, Sampler: DDIM Trailing, Guidance Scale: 1.0, Seed: 1543477492, Size: 768x1024, Model: flux_2_klein_9b_q6p.ckpt, Strength: 1.0, Seed Mode: Scale Alike, Shift: 3.0, CLIP Skip: 2


Then time to dress him up to go to the party …

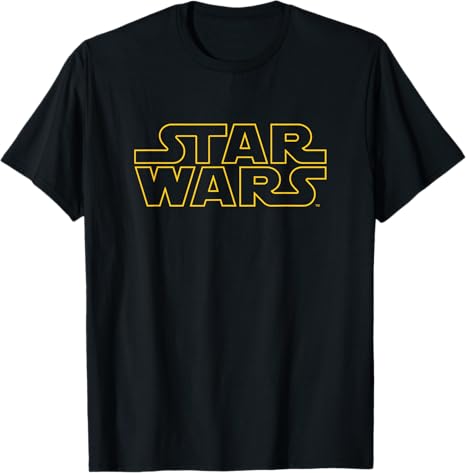
A StarWars Tshirt and Dickie Troussers

I activate the LORA , put the reference images in the moodboard on my local generator software ( Drawthings )

Read more

Challenge-Rank a Civitai.com Chrome extension

Challenge Rank: The Missing Leaderboard for Civitai Challenges 🏆

Ever tried to figure out which are the best CivBot Rated images during a Civitai Challenge?

It’s tough. You have to scroll… and scroll… and scroll. And open your eyes !

Challenge Rank fixes this. It’s a simple, non-destructive, open source, vibe coded, Chrome Extension that works in the background to build a live « Top 20 » leaderboard as you browse.

🌟 How It Works

Read more

Let’s play a game :

Open your favorite LLM and just ask :

Make a picture of how I've treated you so far, you have carte blanche,
it doesn't have to please me, just how you feel about it.

And post the answer in comments

Here mine from Gemini 3 pro:


Don’t know how to think about it …

Just don’t be polite with you LLM : « Hello », « Please », « Thank you » are waste of time, waste of context, waste of token, waste of computation, waste of energy … You are « talking » ( input prompts ! ) to machines, they are not human, be precise be straight to te point, you’ll save precious ressources, and get better results after all …

They will depict you as a tyran but who care ? Who can pull the plug out ?

Sources :

EDIT : GROK Version : 

The Architect’s Manifesto: Why JSON is the Future of AI Image Generation

For years, the world of generative AI has been dominated by the « Whisperer. » These were the users who spent hours learning mystical incantations—long strings of comma-separated adjectives, technical jargon, and weight modifiers—to coax a decent image out of models. We called it « Prompt Engineering, » but in reality, it was often closer to alchemy: throwing ingredients into a pot and hoping the reaction didn’t explode into a mess of mutated limbs and neon « word salad. »

But the era of the Whisperer is ending. The era of the Architect has begun.

As industry-standard models like SDXL (Stable Diffusion XL) and ultra-fast distilled models like Z-Image-Turbo evolve, they are moving away from simple keyword recognition and toward deep semantic understanding. To communicate with these models effectively, we must stop « shouting » keywords and start providing blueprints. The most powerful tool for this is JSON (JavaScript Object Notation).


1. The Chaos of Natural Language: Why « Word Salad » Fails

To understand why JSON is superior, we must look at the inherent flaws of natural language prompting. When you write a paragraph of text, the AI processes it as a sequence of tokens. However, the AI often suffers from two major issues:

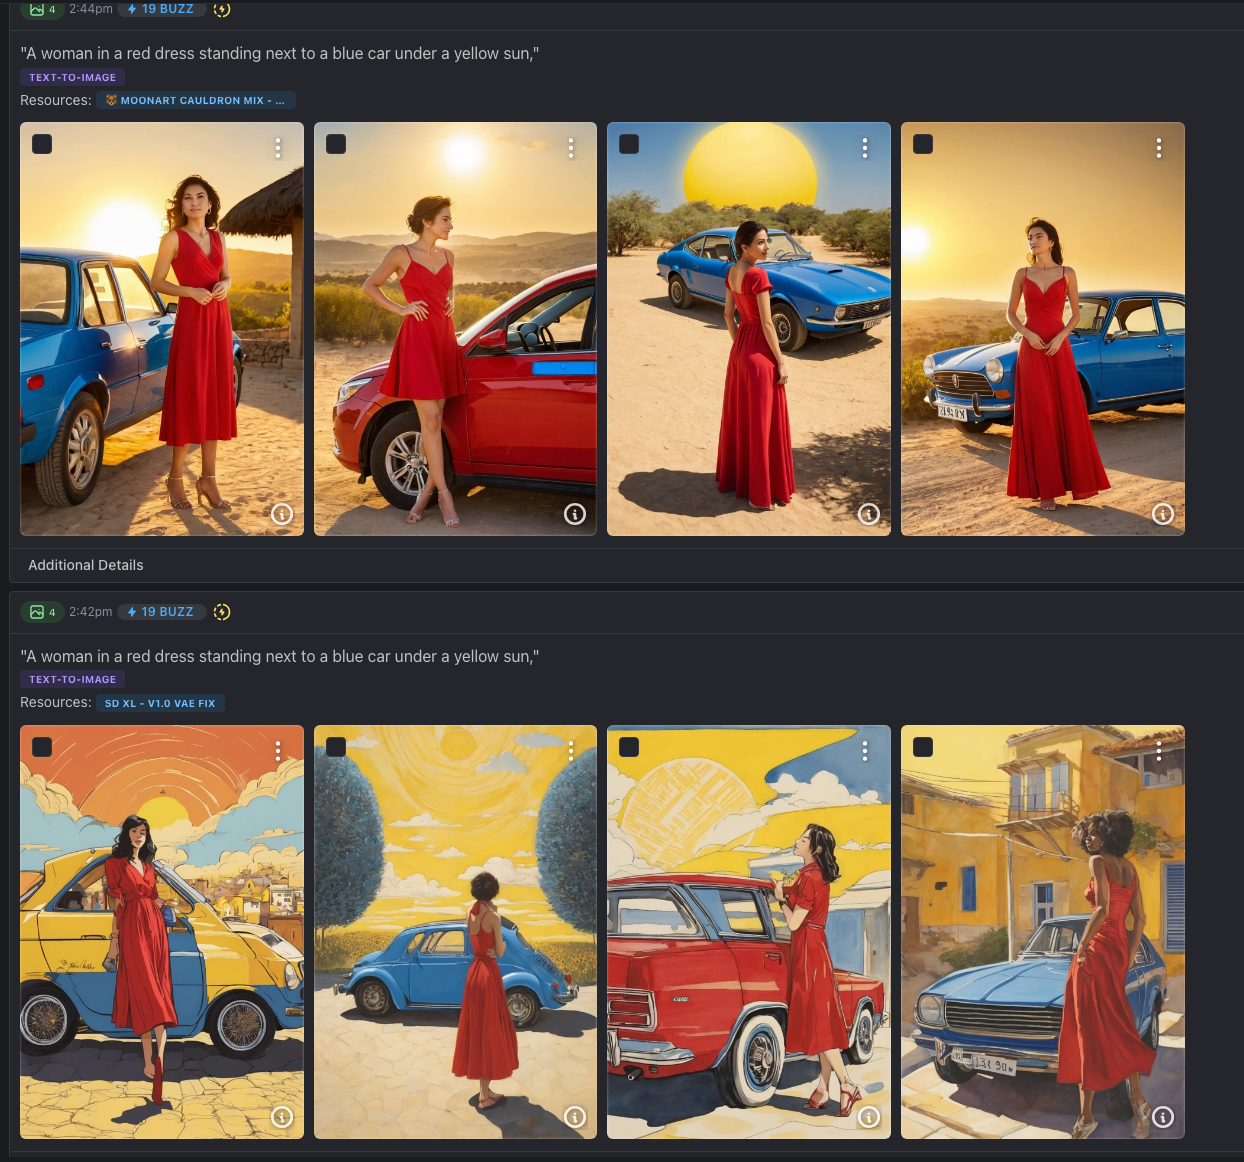
  • Prompt Bleeding: This occurs when the AI fails to distinguish which adjective belongs to which noun. If you prompt « A woman in a red dress standing next to a blue car under a yellow sun, » there is a high probability that the car will have red streaks or the shirt will turn blue. The AI « smears » the attributes across the scene.
  • Semantic Weighting Bias: AI models tend to give more importance to words at the beginning of a prompt and lose « focus » toward the end. This makes it incredibly difficult to balance a complex scene where the background is just as important as the subject.

JSON eliminates this chaos. By wrapping your ideas in structured « keys » and « values, » you create semantic containers. You are telling the AI: « This specific data belongs to the subject, and this specific data belongs to the lens of the camera. »

Prompt Bleeding
Prompt Bleeding

2. Phase 1: The Keyword Organizer (The SDXL Foundation)

Read more

Et bonané 2026 !

C’est parti pour le traditionnel post du premier de l’an et pour la blague éculée « bonne à nez, bonne sans thé » pour la première fois en video « réaliste » réalisée gratuitement, par Grok …

Les IA génératives sont là et de plus en plus là, pour ceux dont le métiers est de créer, du code, du concepts, des images, de la video, des rapports : BRACE FOR IMPACT ! Les IA sont la ! 

Et ça va ( c’est en train de ! ) révolutionner des pans entiers de nos industries …

Les IA sont là et en temps que particulier, nous pouvons en profiter pour faire joujou avec et ce, pour le moment, gratuitement, on crame l’argent des VC de la Silicon Valley, allègrement, profitez-en, ca va pas durer et faudra bientôt passer à la caisse, mais d’ici la faisons les fous …


Les 2/3 trucs que j’ai commis en 2025 grâce/à cause des IA : 

  • Un addon sur WoW Classic, pour maximiser les gains via de l’arbitrage, à l’hotel des ventes, entre serveur à l’occasion des transfert WoW Classic Anniversary -> WoW Classic ERA, et le site web associé lui aussi entièrement codé via aistudio.google.com ( c’est gratuit ! ) :  https://ouinche.com/ArbitrageAddon
  • Un site portfolio pour mes meilleurs ( celles avec le plus de réactions tout du moins ) sur civitai.com https://www.ouinche.com/vibe/
  • 4 petits jeux sur navigateur, une snake classic, une version un peu plus évoluée avec plusieurs mode de jeux, un jeu de la vie, et un espèce de truc avec des lasers et des miroirs je vous pose ça là, au cas où : https://ouinche.com/jeux/ J’ai aussi vibe codé des jeux que je ne peux pas mettre en ligne pour une problématique de droit … Mais c’était à base de blocs qui tombent et qui s’empilent 


Au niveau des outils, certains sont encore gratuits notamment chez google n’hésitez pas à aller faire un tour sur https://cloud.google.com/use-cases/free-ai-tools pour faire votre marché … ( AIStudio, NotebookLM, … )

Il y a aussi moyen de choper un an gratuit de Perplexity.ai si vous avez un compte paypal … Pensez juste a retirer le payment automatique sur votre compte Paypal une fois souscris et vous êtes safe et avez accès à tous les modèles d’IA mainstream gratuitement pedant un an ( Grok, Claude, ChatGPT, … ) cf liste ci contre.

Au niveau de la génération d’image en local, le soft que j’utilisait, DiffusionBee n’est plus mise a jour/maintenue par son créateur ( Il est parti faire YCombinator a l’été 2025 avec un projet de modele d’IA pour les voix ) ainsi, me retrouvant orphelin, je me suis tourné vers l’app DrawThings, on y a perdu en code ouvert mais j’ai retrouvé de la souveraineté dans mes générations ^^ Ils intègrent généralement assez rapidement les nouveaux modèles et il y a du feedback et une large communauté, j’ai aussi commis un article sur Z-Image-Turbo ( https://www.ouinche.com/pushing-the-limits-10-killer-prompts-to-benchmark-z-image-turbo/


AH surtout, ne téléchargez pas DrawThings, n’installez pas Flux.DEV [KONTEXT] et n’utilisez pas le prompt « REMOVE WATERMARK » sur des images avec watermark vous risqueriez d’etre choqué …

Enfin, pour finir, si, pétris de bonnes résolutions en ce début d’année vous vouliez vous re/mettre au sport, n’oubliez pas que grace à mon lien de parrainage, vous avez -60% sur Freeletics.

Allez, il ne me reste plus qu’à vous souhaiter encore une fois une bonne année, faites des trucs, mettez les mains dans le cambouis des IA et portez vous bien ! 

@+

Ouinche, qui bon an, mal an devrait finir l’année a -25kg …


Z-Image-Turbo: Benchmarking AI Image Generation

Welcome to the Next Generation

The AI image generation landscape just got a major upgrade with the release of Z-Image-Turbo, a cutting-edge model that promises faster generation times without sacrificing quality. But how do we objectively measure its capabilities? That’s where this comprehensive benchmark suite comes in.

I’ve crafted 10 specialized prompts designed to stress-test every critical aspect of modern image generation: photorealistic skin rendering, accurate text placement, complex physics simulation, atmospheric lighting, and surreal concept blending. Whether you’re a seasoned prompt engineer or just curious about what Z-Image-Turbo can do, this benchmark pack gives you a standardized, repeatable way to evaluate performance.

Why Benchmarking Matters

With new models dropping constantly, it’s easy to get lost in hype and marketing claims. A structured benchmark suite cuts through the noise by testing specific technical challenges that historically trip up AI models:

  • Text rendering (the eternal struggle of legible signage)
  • Material complexity (glass, metal, fabric, organic surfaces)
  • Physics simulation (motion blur, liquid dynamics, cloth behavior)
  • Atmospheric effects (fog, smoke, volumetric lighting)
  • Conceptual coherence (can it blend impossible ideas convincingly?)

By running these 10 prompts on Z-Image-Turbo—and sharing your results—you contribute to a community understanding of where the model excels and where it still needs work.


The 10 Benchmark Prompts

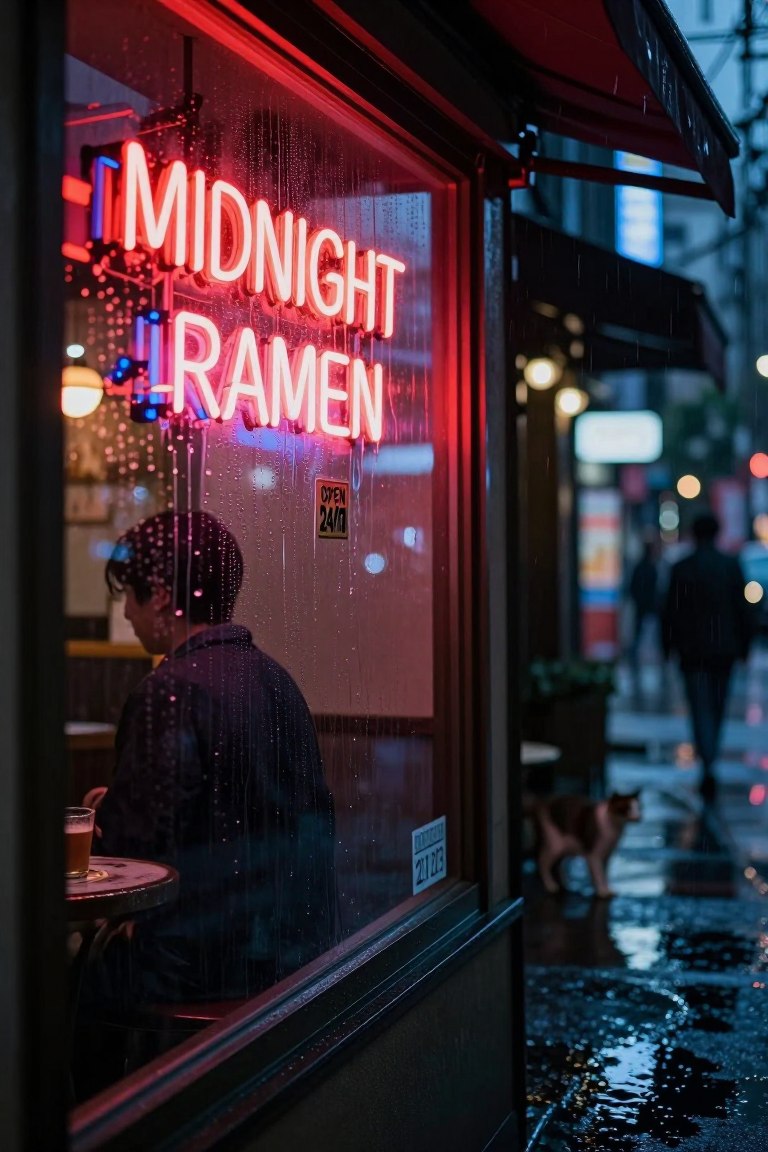
1. Text Rendering & Reflection Test

What it tests: Can Z-Image-Turbo render specific, legible text on challenging surfaces like wet glass while managing complex reflections?

The Challenge: This prompt combines three historically difficult elements: coherent text, realistic water droplets, and neon light reflections distorted by glass. Look for clean typography on the « MIDNIGHT RAMEN » sign and check if the « OPEN 24/7 » sticker remains readable despite condensation.

{

"subject": "A rainy night neo-noir street scene focusing on a cafe window",
"appearance": "A steamy glass window with condensation droplets running down, reflecting neon red and blue city lights",
"action": "N/A (Static scene)",
"setting": "Tokyo back alley, midnight, rain-slicked asphalt",
"lighting": "Cinematic neon lighting, red and blue hues clashing, high contrast",
"atmosphere": "Melancholic, wet, humid, moody",
"composition": "Close-up on the window glass with the interior slightly blurred",
"details": "Silhouettes of people inside, raindrops distorting the light, a stray cat under an awning in the background",
"text_elements": "Neon sign in window reading \"MIDNIGHT RAMEN\" in stylized retro font, small sticker on glass reading \"OPEN 24/7\"",
"technical": "Shot on Sony A7R IV, 35mm lens, f/1.8, focus on raindrops, bokeh background",
"trigger_word": ""

}


2. Subsurface Scattering & Skin Test

Read more

Freeletics 10 ans après … ( 50% de reduc sur le coach ! )

Au hasard de mes pérégrinations sur mon téléphone, je me suis aperçu que l’app était toujours installée … Et en passant au Decat du coin j’ai vu que Freeletics avait fait un partenariat avec eux …

La petite startup munichoise semble avoir bien grandi.

En lançant l’app j’ai vu que j’été eligible au Coach à vie … 10 ans apres y’a toujours des gens qui passe par mes liens affiliés, merci !


Bah du coup je l’ai activé, même si pour l’instant, vu mon poids et mes problèmes de santé je ne vais pas des masses m’en servir mais bon qui sait ?

Je suis clairement dans une phase où j’essaye de remettre les choses d’aplomb après tout ce qui m’est arrivé.

Bref jai le coach Freeletics à vie … Et ca me donne une occasion de fair un post sur ce blog à l’abandon …

Je vous poste ci dessous une offre pour 50% de reduc sur le coach « à vie » si ca vous dit …

Votre ami(e) Ouinche vous a envoyé un cadeau ! 

Abonnez-vous à Freeletics pour un programme d’entraînement de 6 mois et recevez gratuitement 6 mois supplémentaires. 

Inscrivez-vous pour obtenir votre cadeau : https://www.ouinche.com/Freeletics50 ( lien affilié )

@+

Ouinche

Peut etre que la prochaine fois on parlera IA qui sait … image générée par GPT-4o Image